Podonos Blog
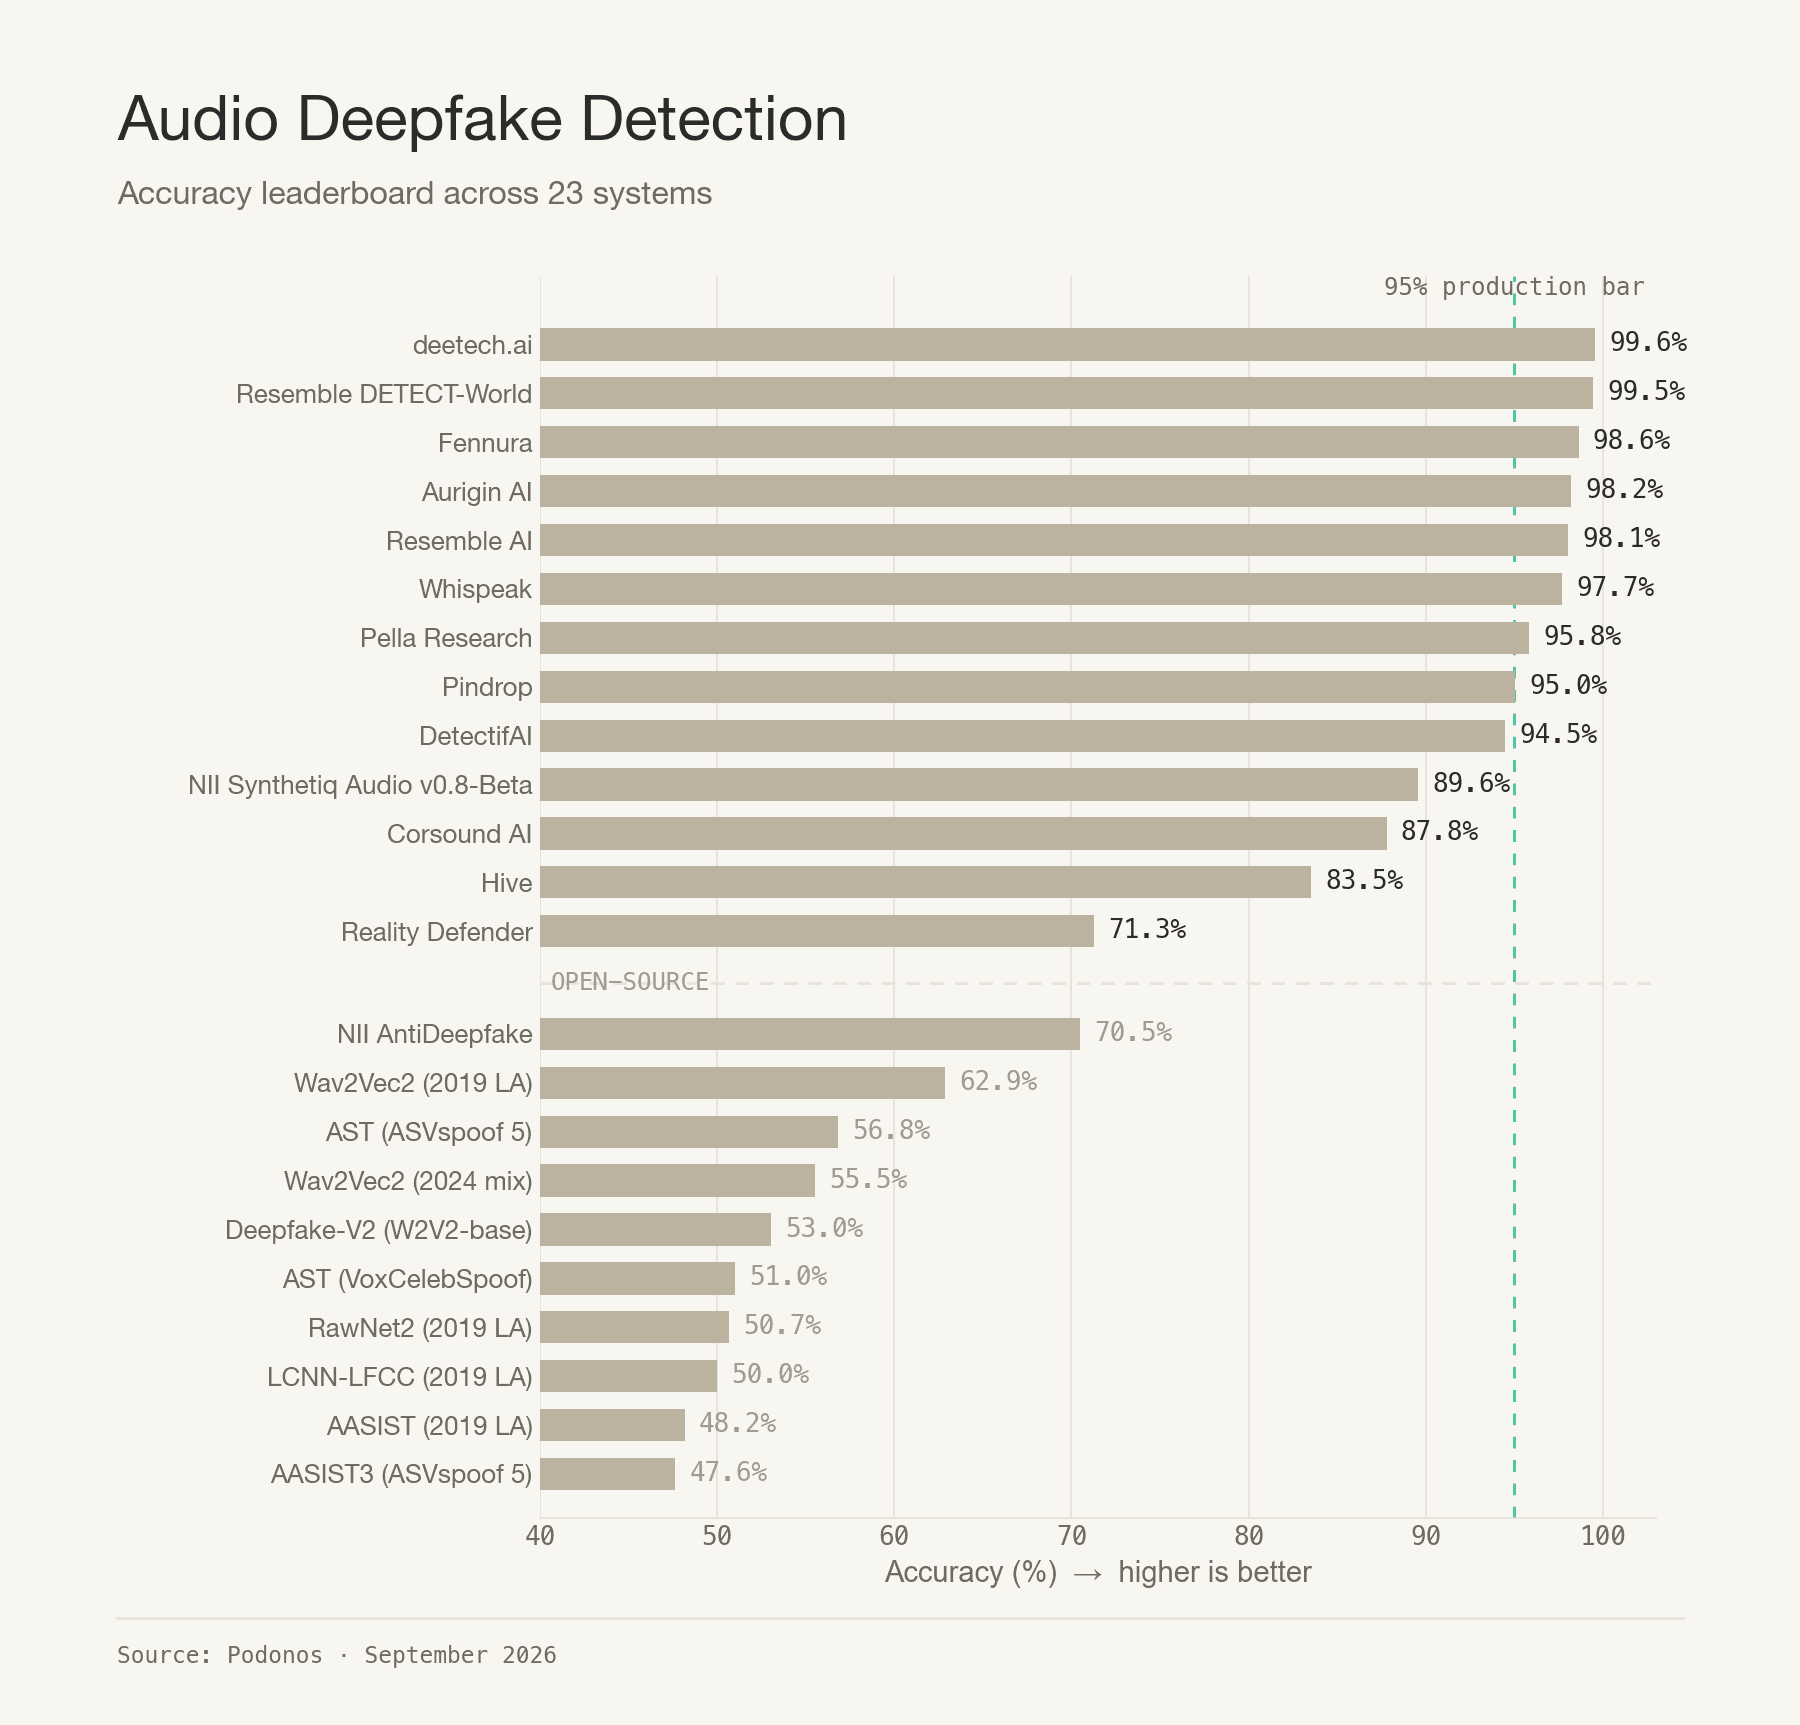
Five new systems later, our audio deepfake detection benchmark has grown to 23 entries, and eight systems now clear 95% accuracy.
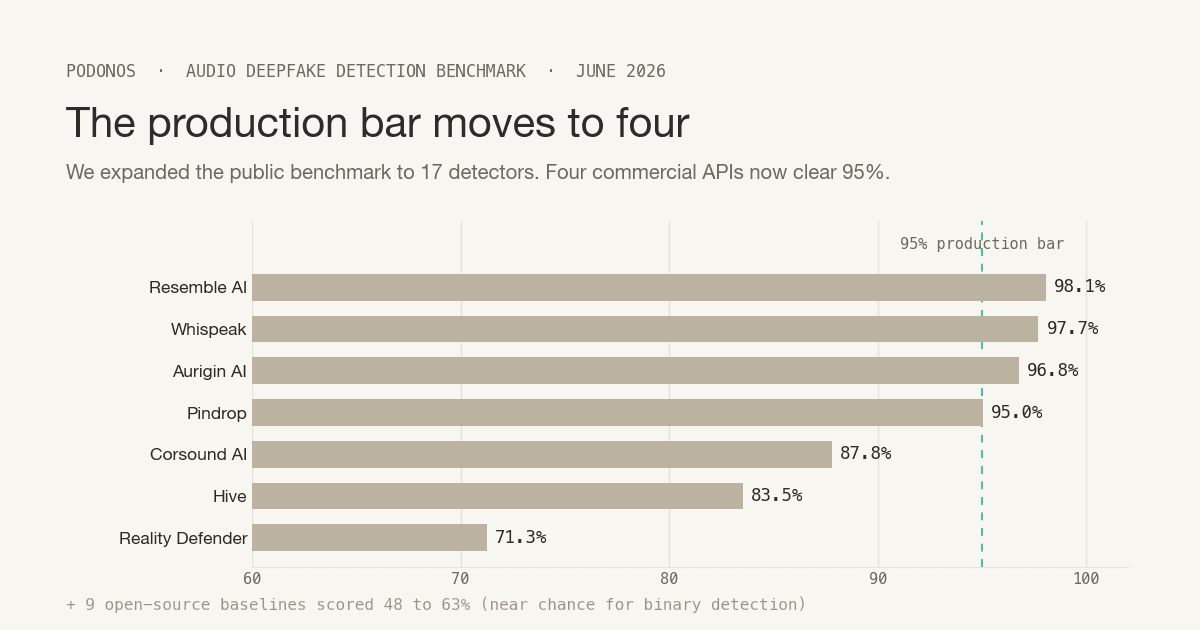
When we last published this benchmark, four commercial systems sat above 95% accuracy and none of nine downloadable open-source models scored above 63%.
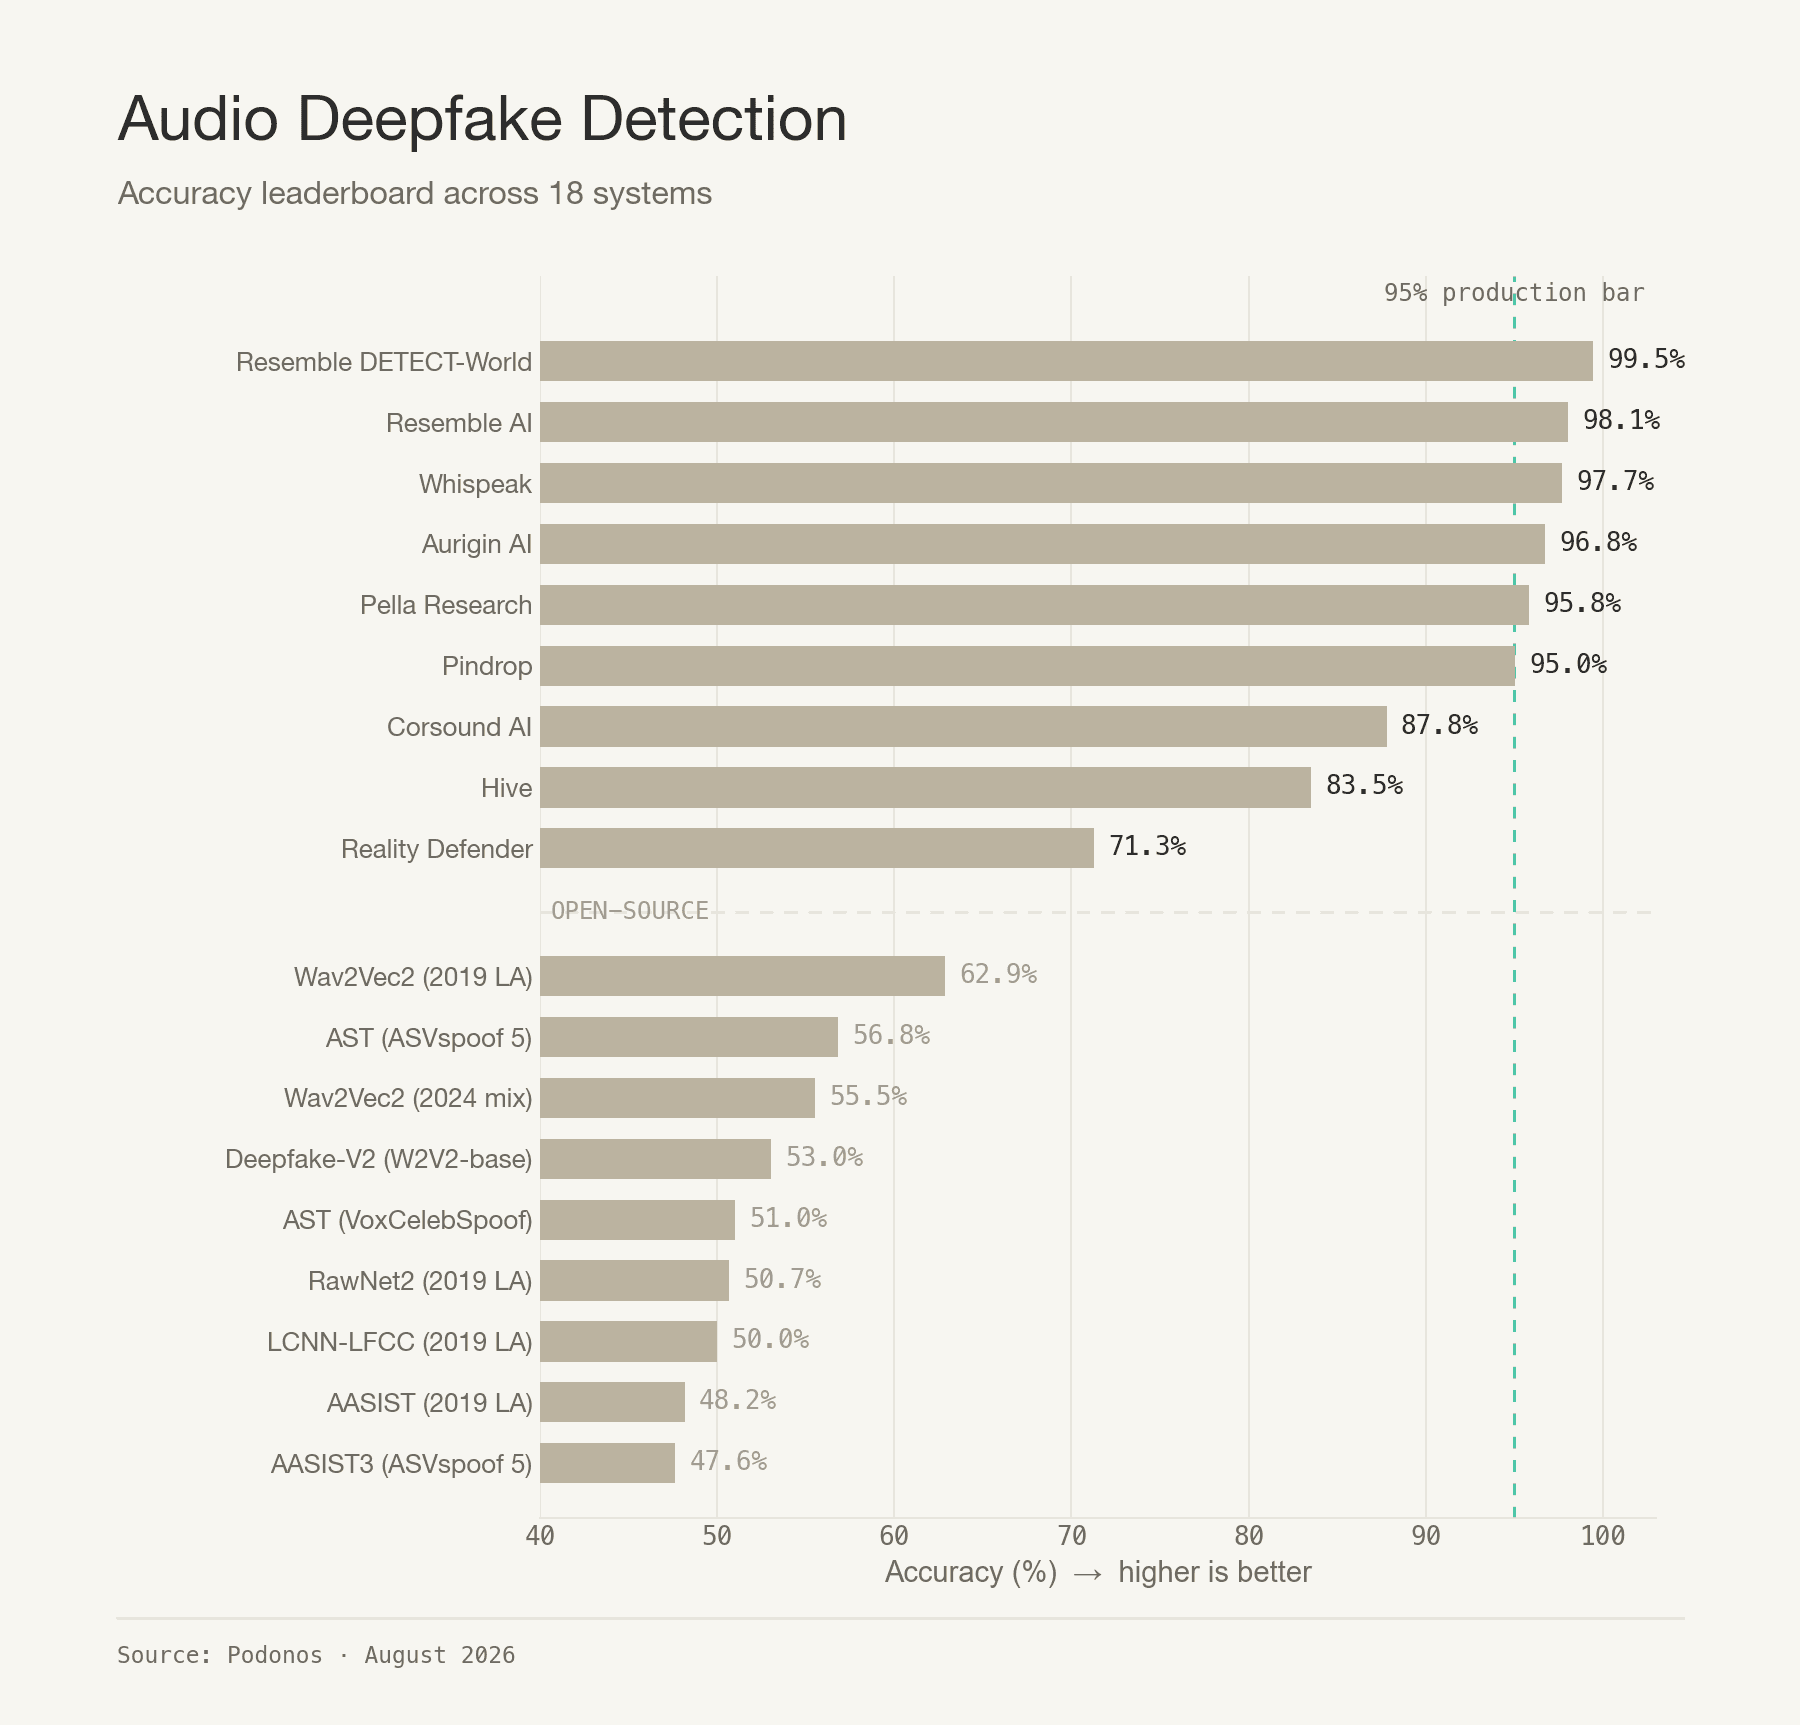
Nine new systems later, the top of our audio deepfake detection benchmark is crowded, the open-source gap is wider than ever, and speed sets systems apart.
Naturalness and preference diverge: our US English TTS benchmark ranked Deepgram Aura 2 #1 for naturalness and Rime Arcana v3 #1 for preference.
Every audio deepfake vendor reports accuracy around 99%, but none of those numbers are comparable: each comes from a test set the vendor controls.
After meeting speech and audio researchers and reviewing their applications, we announce the teams selected for the Podonos Research Support Program.
Resemble AI's open-source Chatterbox showed open TTS models are viable alternatives to proprietary systems. Chatterbox Turbo takes that a step further.
Human evaluation gives voice AI teams the best insight but takes time, and fast AI evaluators often miss human perception. Podonos Flash changes that.
Podonos has raised $2.4M in pre-seed funding to tackle voice AI evaluation, led by Serac Ventures with participation from Naver D2SF and KAIST Ventures.
The Wizard feature has launched. It guides you through designing an evaluation, blazing fast, with no audio files or script development needed.
With automation, teams can generate thousands of audio samples and collect as many human evaluations. The real challenge: what to do with all that data?
As voice AI advances, evaluating it accurately gets harder. Whether for naturalness, emotion, or speaker similarity, evaluation reliability is critical.
Many voice AI teams perfect their models in English first. But when a model expands to global markets, its performance doesn't always translate.
How does Google's new Gemini 2.5 text-to-speech model perform against ElevenLabs' Multilingual V2? We ran a head-to-head evaluation to find out.
AI model evaluation isn't just a final step. It's the launchpad. Resemble AI used Podonos to benchmark Chatterbox, its open-source TTS model.
How good are public text-to-speech APIs? Error rates miss small naturalness and quality errors, and preference rankings miss the deeper aspects of voices.
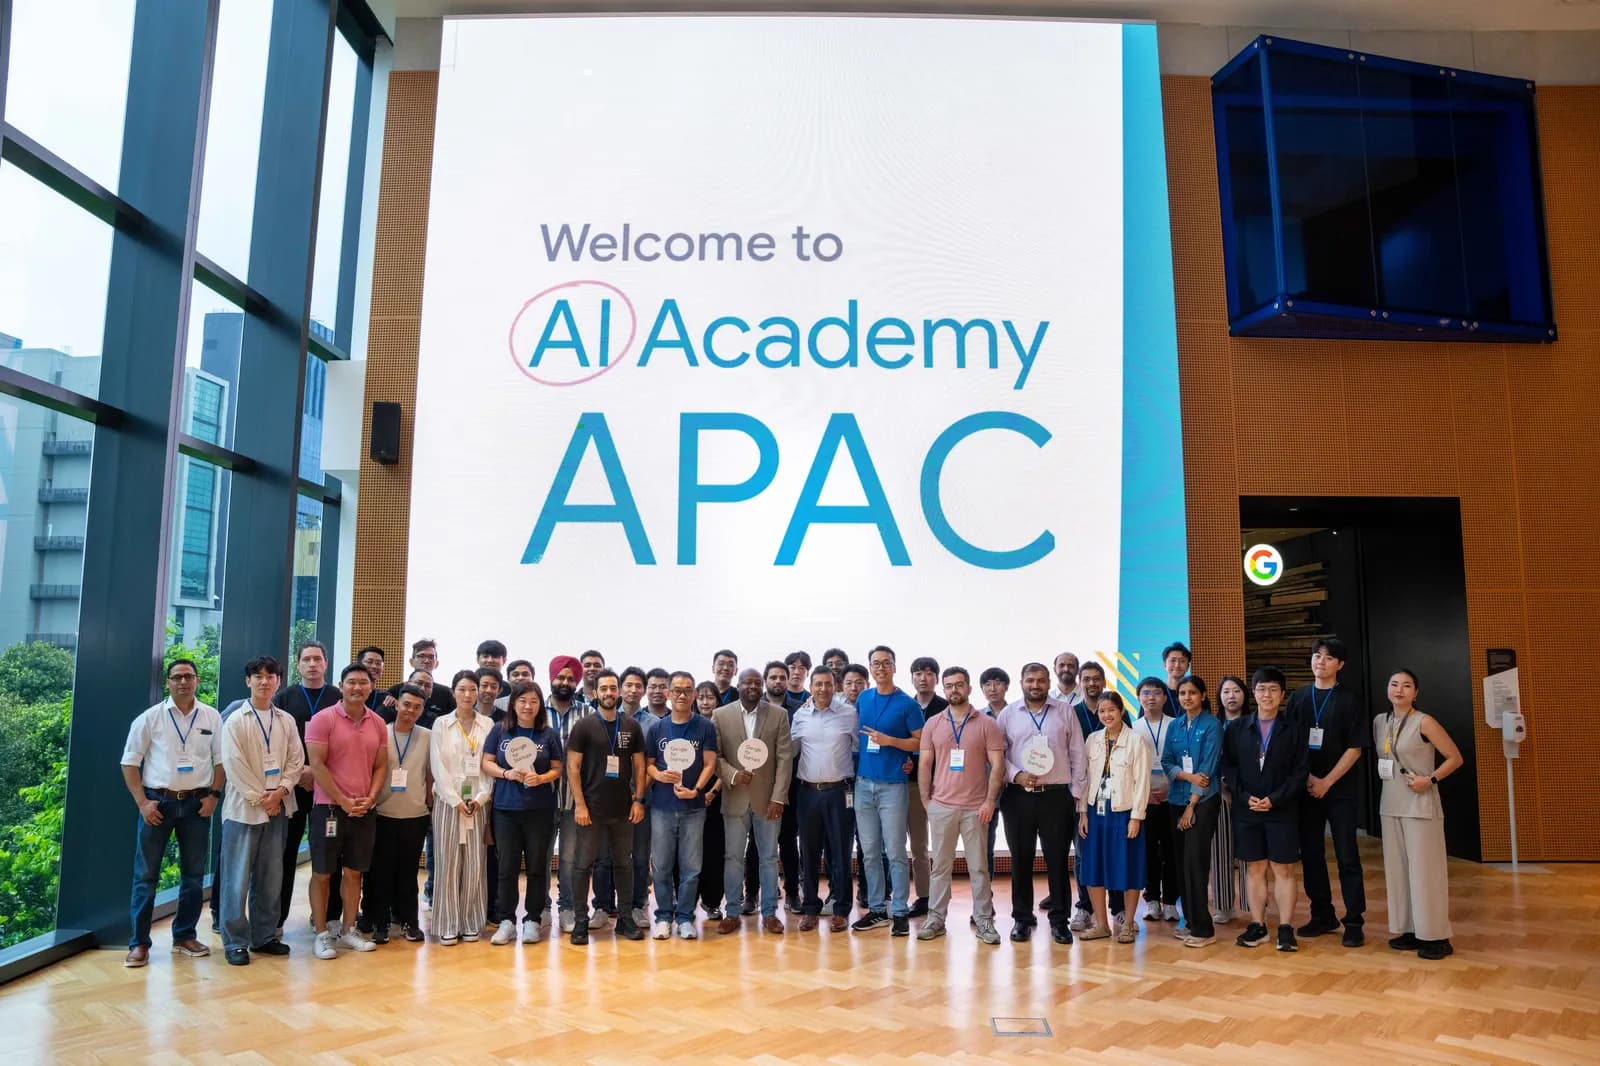
Podonos joins the Google for AI Academy program, partnering with Google on technical innovation, go-to-market, and founder networks.
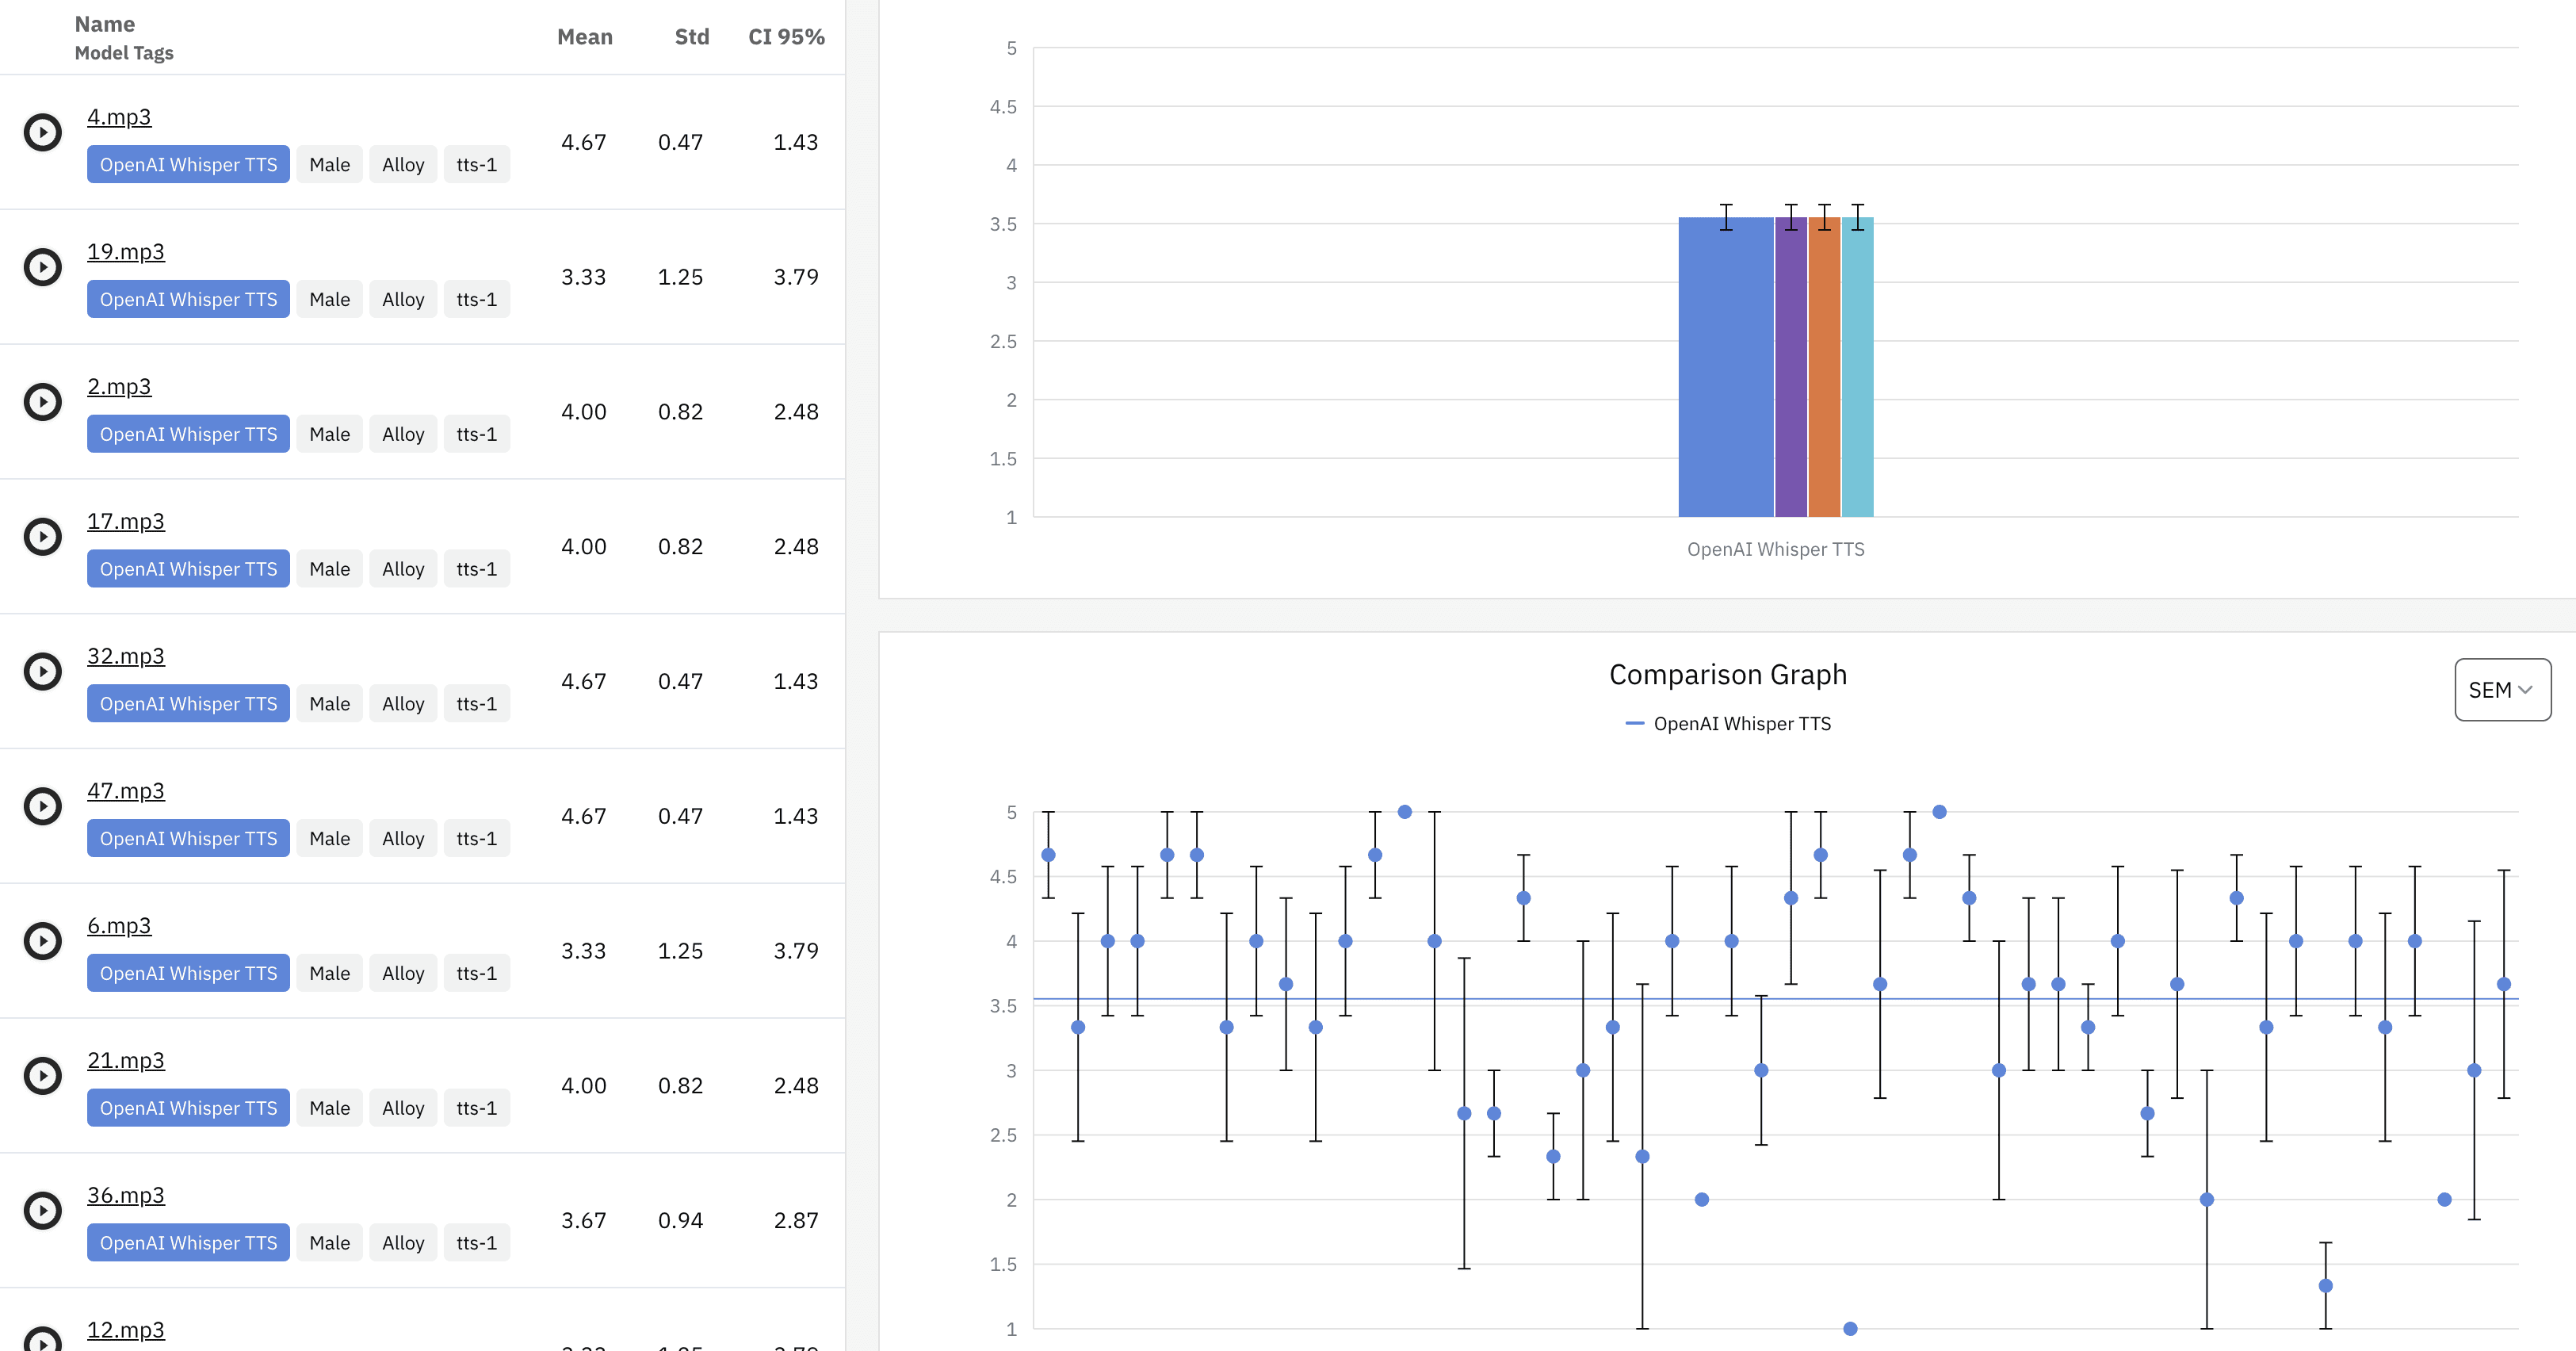
How well does a TTS model work for your language? As a first step, Podonos releases evaluation results of OpenAI's text-to-speech model for Korean.
Podonos has joined the NVidia Inception program, with NVidia support for AI model development, go-to-market, and investor connections.
Subjective audio evaluation is the assessment of generated or processed audio and speech by human listeners, who judge its effectiveness and quality.
Improve your model with trust