Subjective audio evaluation is the assessment of generated (e.g., by using generative AI models), processed (noise reduction, compression, echo cancellation, and so on) audio or speech by human listeners. The human evaluators play a crucial role in determining the effectiveness and quality of the audio output.
The main goals of subjective audio evaluation include:
- Naturalness: How closely does the AI-generated voice resemble a human voice?
- Quality: What is the overall quality level of the audio or speech? How much noise do you hear?
- Similarity: How similar is the AI-generated speech to the intended target or original speech? How similar is the voice of the French-speaking Elon Musk to his original English-speaking voice?
- Preferences: What are the listeners' preferences among different versions of AI-generated audio?
The ultimate goal is to gain insights into the usability of the output, and to find ways to further improve generative AI models, speech enhancement techniques, noise reduction algorithms, and other related technologies.
However, is this process simple? In reality, it is not unfortunately. Before executing such evaluations, you need to address numerous preliminary questions:
- What is the goal of the evaluation?
- Who will participate in the evaluation session?
- How will you find and recruit the human evaluators?
- How to qualify/disqualify the human evaluators before & after the evaluation?
- What acoustic environment is relevant or acceptable?
- Which evaluation type and scale should you use?
- How will you compensate the evaluators from all over the world?
- How will you analyze the data collected?
- And many more logistical and methodological considerations.
Assuming that you have relevant answers to most of the questions, let’s delve deeper into the evaluation types and scales. There are established subjective evaluation standards, recommended by the International Telecommunication Union (ITU) such ITU-T P.835, ITU-R BS.1534 (MUSHRA), and de facto standards used within the industry.
Assume you want to evaluate how natural the AI-generated human voice is. One widely used evaluation method for this type of assessment is the Mean Opinion Score (MOS). In this method, evaluators rate the naturalness of the audio on a scale from excellent, good, fair, poor, to bad. For statistically meaningful results, you must:
- Ask multiple human evaluators to listen to each audio file.
- Compute various statistical analyses including mean, median, standard deviation, and confidence intervals.
Typically, you would evaluate multiple audio files containing generated speech. By compiling all the data, you can compute overall naturalness statistics and create a table such as:
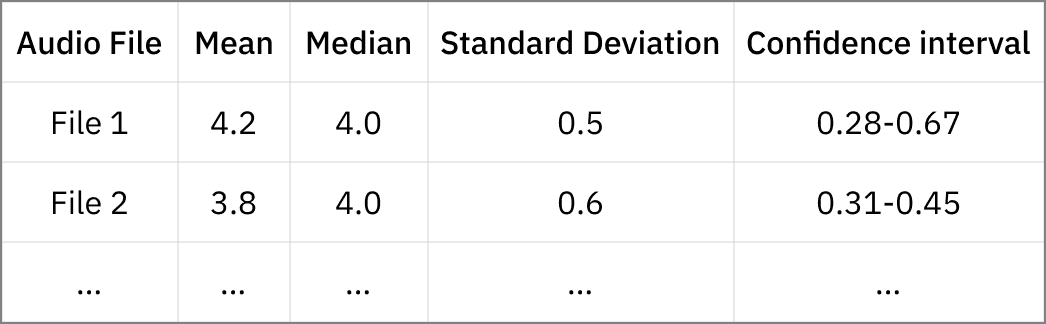
Voilà! Now you can draw a first insight into how natural the output speech is.
This example, however, overlooks many sophisticated details as the actual evaluation process is much more complex and cumbersome. Evaluations must consider the diversity of listeners, potential biases, the context in which the audio will be used, and the specific attributes of speech quality and naturalness that are most relevant to the application at hand.
In conclusion, subjective audio evaluation is a critical process in the development and refinement of AI-generated audio technologies. By thoroughly planning and executing these evaluations, we can gather valuable insights that drive the improvement of AI models and audio processing techniques, ultimately leading to more natural and high-quality audio experiences.