Podonos just raised $2.4M in pre-seed funding

We are excited to share that Podonos has raised $2.4 million in pre-seed funding to tackle one of the most overlooked challenges in voice AI — evaluation. The round was led by Serac Ventures with participation from Naver D2SF and KAIST Ventures.


Why Evaluation Matters

Voice AI is advancing at an incredible pace. Text-to-speech, voice cloning, speech recognition, and multilingual assistants are becoming part of our daily lives. But one critical question remains: how do we know if these models are truly ready for the real world?

Bigger models are being trained, but evaluation often lags behind. Traditional approaches are slow, unscalable, and inconsistent. This creates blind spots, and issues are often discovered only after products are deployed. For industries like healthcare, finance, or automotive, those risks are too high.


How Podonos Helps

Podonos was founded to close this gap. Our human-in-the-loop platform evaluates voice AI models across naturalness, similarity, emotion, recognition accuracy, and more. Evaluations are completed in under 12 hours, even across thousands of audio samples and multiple languages.

This speed gives product teams a feedback loop they can act on. Instead of waiting weeks, they can iterate quickly, validate their results, and build with confidence.

As our founder and CEO, Dr. Soohyun Bae, explains:

“Everyone is focused on training bigger models, but few talk about how to measure what works in the real world. Evaluation is where real improvements happen.”


What This Funding Means

With this funding, we will expand our engineering team, strengthen post-analysis tooling, and launch in key global markets including the U.S., Europe, and Southeast Asia.

Kevin Moore, partner at Serac Ventures, shared:

“One of the biggest challenges in adopting voice AI is dealing with unknown issues. Identifying and fixing them before launch is critical to building customer trust. Podonos makes the unknowns clear and helps customers launch with confidence.”


Looking Ahead

We are building the trust layer for voice AI. This funding helps us move faster toward a future where models are not just powerful but also reliable, transparent, and ready for real-world use.

If you are building with voice AI and want to ensure your models perform the way they should, get in touch with us at hello@podonos.com.
Other readings

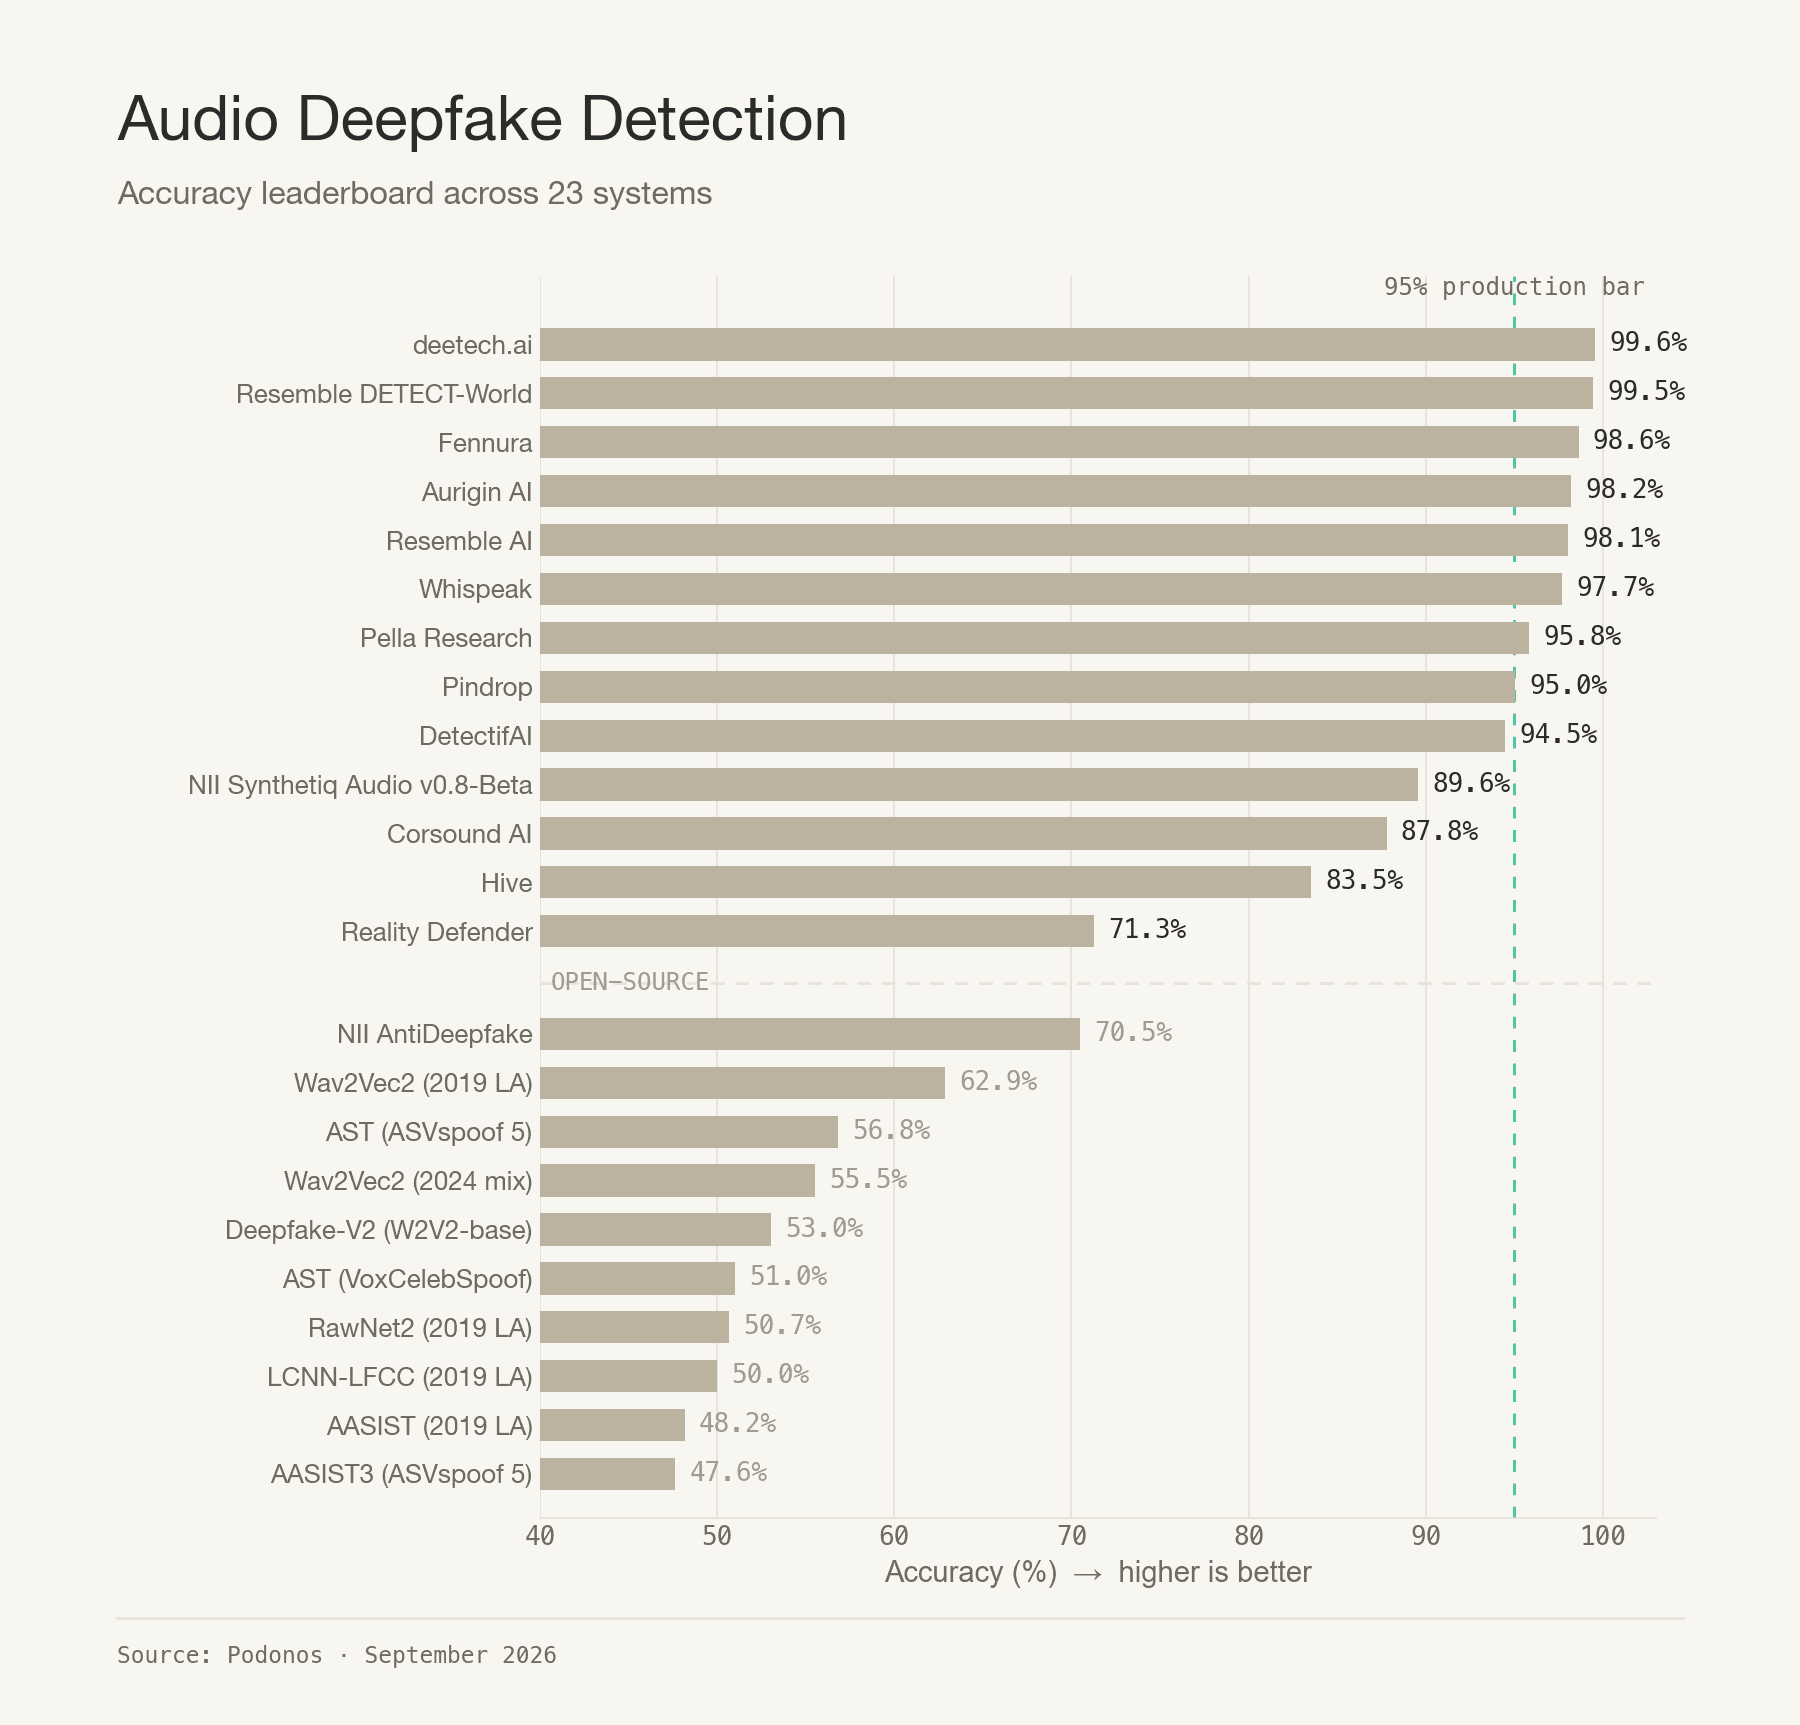
Audio deepfake detection benchmark: deetech.ai takes the top spot

Five new systems later, our audio deepfake detection benchmark has grown to 23 entries, and eight systems now clear 95% accuracy.

|11 min read

Audio deepfake detection benchmark: an open model finally clears the production bar

When we last published this benchmark, four commercial systems sat above 95% accuracy and none of nine downloadable open-source models scored above 63%.

|10 min read

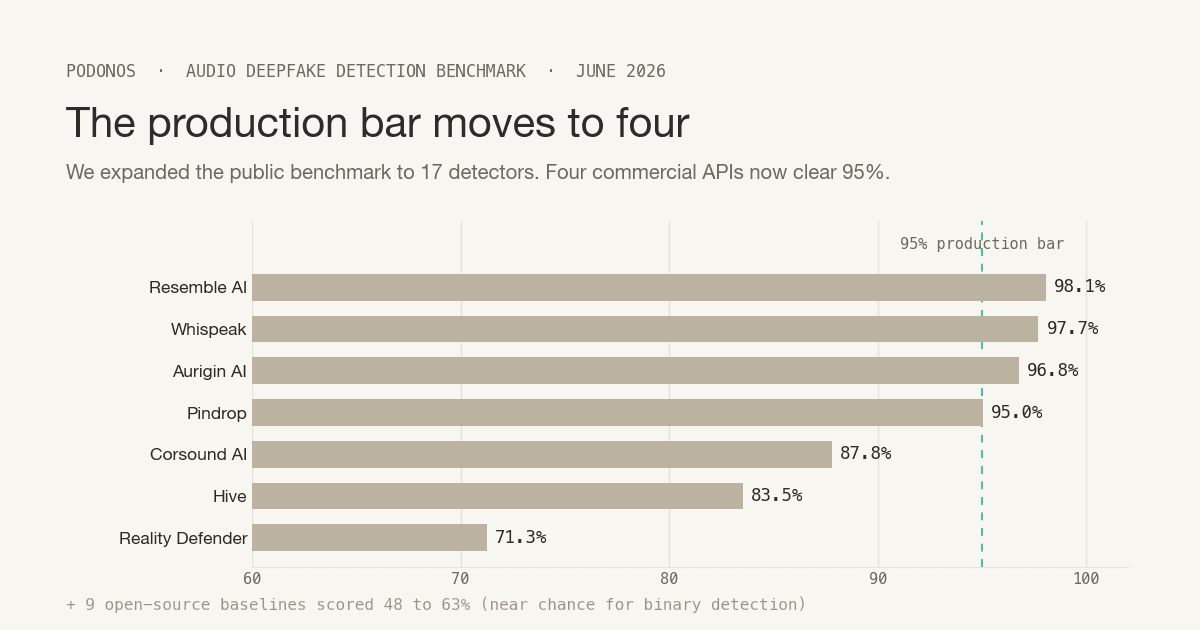
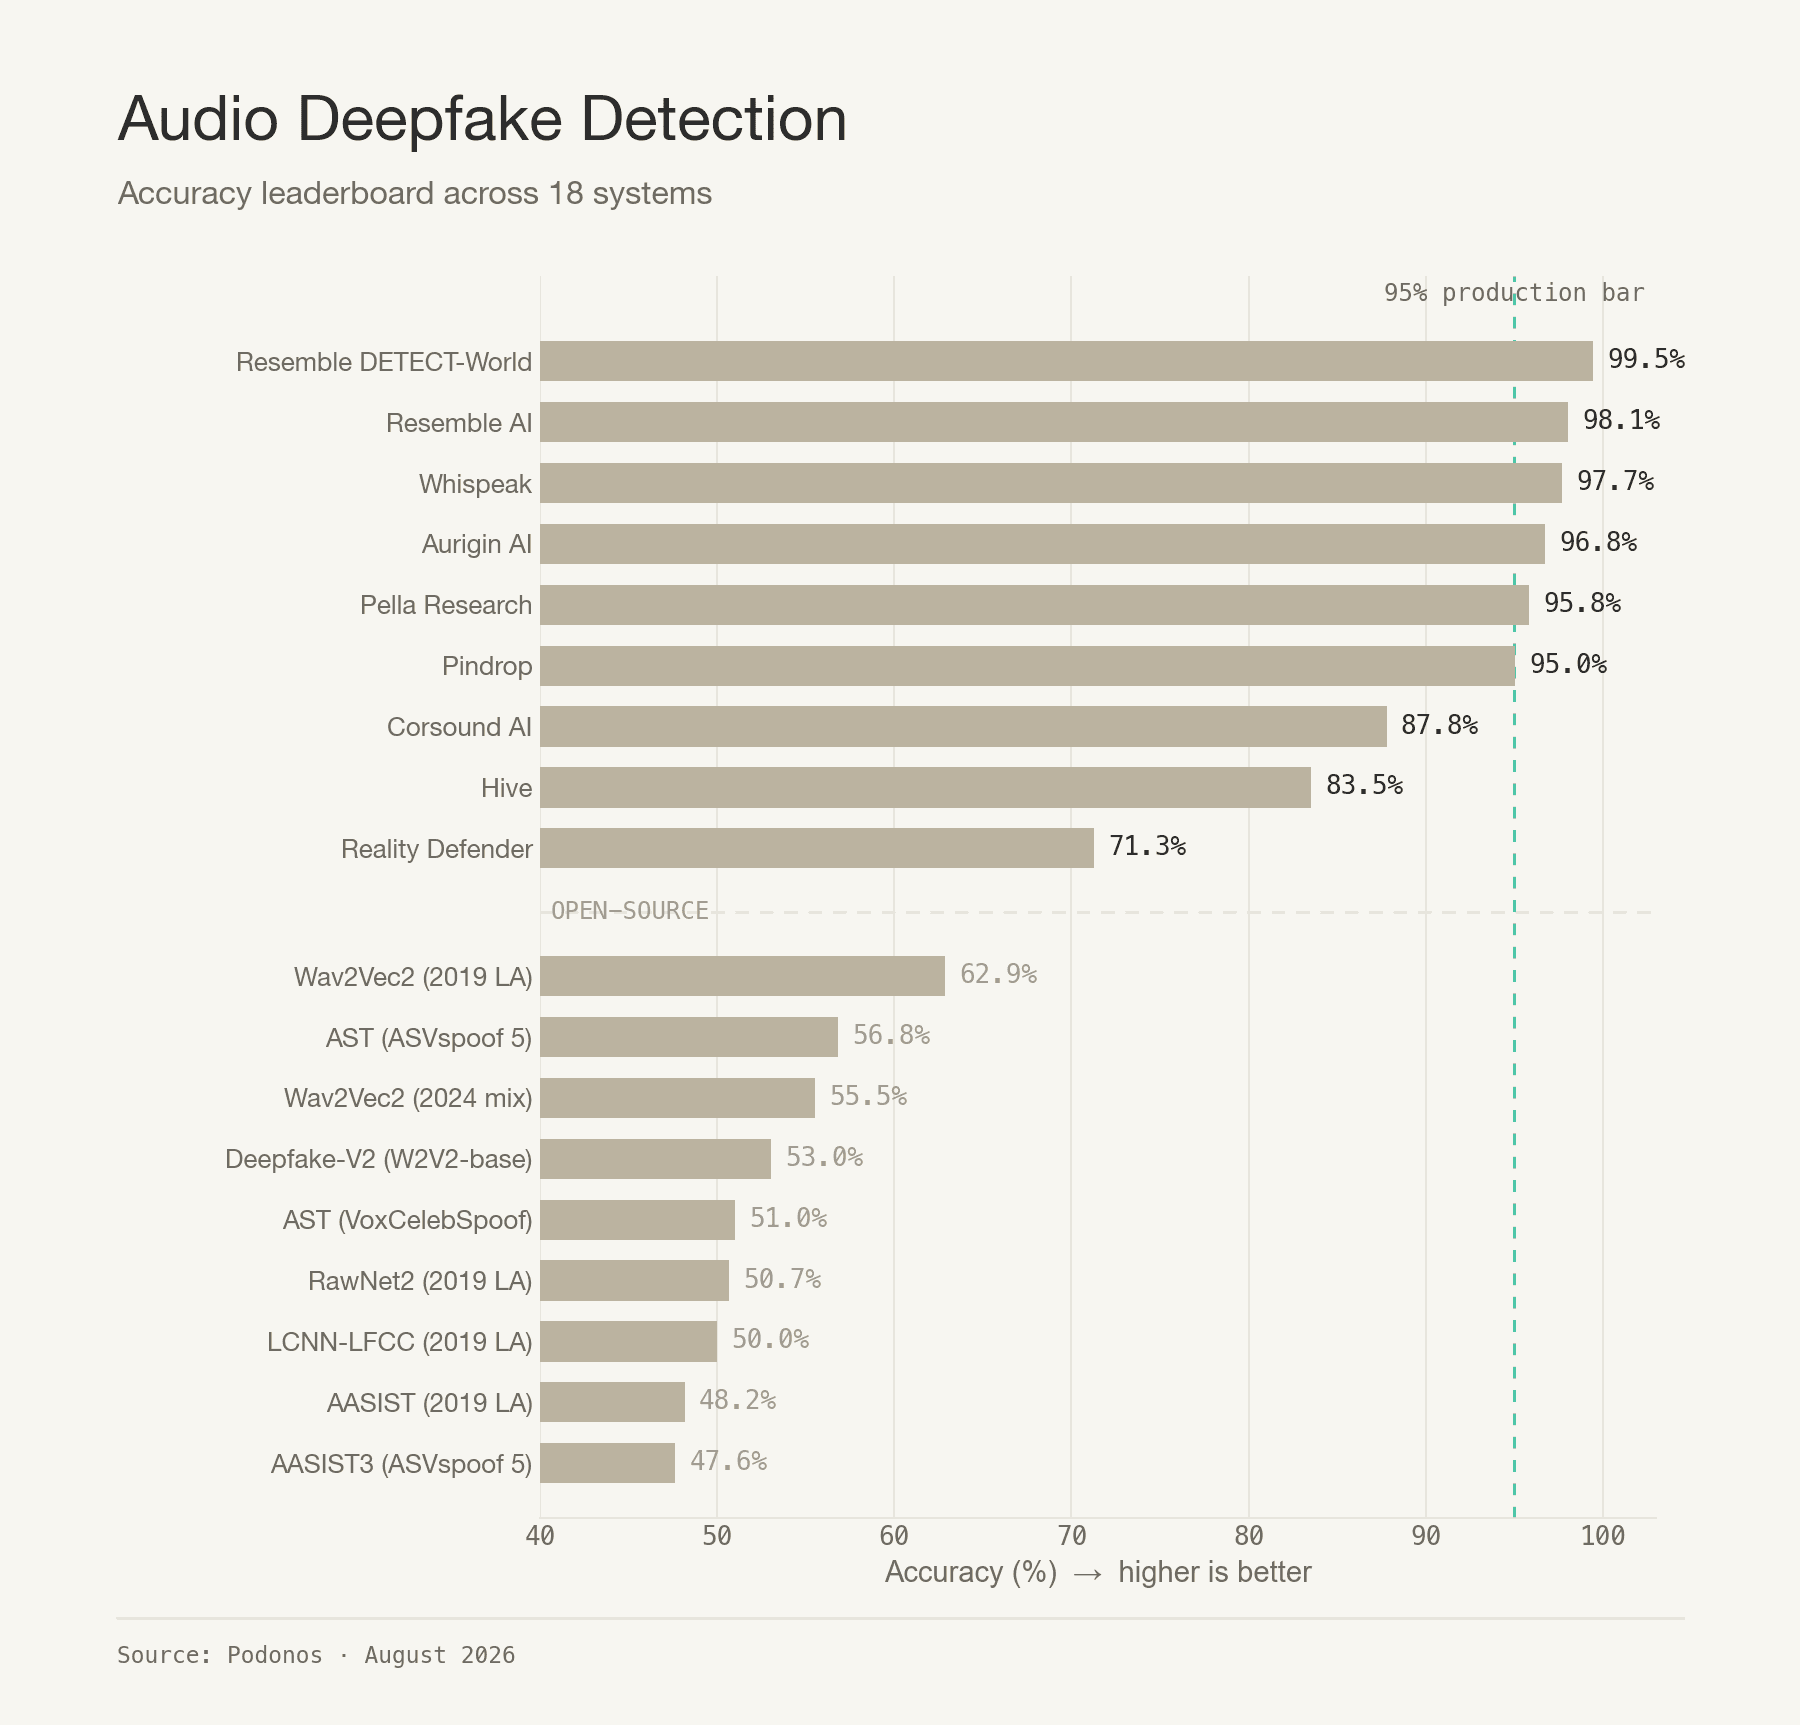
Audio Deepfake Detection Benchmark: the production bar moves to four

Nine new systems later, the top of our audio deepfake detection benchmark is crowded, the open-source gap is wider than ever, and speed sets systems apart.

|7 min read

Natural ≠ Preferred: What Our TTS Rankings Revealed About How Humans Actually Judge AI Voices

Naturalness and preference diverge: our US English TTS benchmark ranked Deepgram Aura 2 #1 for naturalness and Rime Arcana v3 #1 for preference.

|7 min read

Automatic Deepfake Audio Detection Benchmark

Every audio deepfake vendor reports accuracy around 99%, but none of those numbers are comparable: each comes from a test set the vendor controls.

|7 min read

Announcing the Selected Teams for the Podonos Research Support Program

After meeting speech and audio researchers and reviewing their applications, we announce the teams selected for the Podonos Research Support Program.

|2 min read

Benchmarking Chatterbox Turbo: How Resemble AI Evaluated Open-Source Voice AI with Podonos

Resemble AI's open-source Chatterbox showed open TTS models are viable alternatives to proprietary systems. Chatterbox Turbo takes that a step further.

|5 min read

Introducing Podonos Flash

Human evaluation gives voice AI teams the best insight but takes time, and fast AI evaluators often miss human perception. Podonos Flash changes that.

|4 min read

Product Update: Podonos Wizard launch

The Wizard feature has launched. It guides you through designing an evaluation, blazing fast, with no audio files or script development needed.

|2 min read

Why Post-Refining Matters in Voice AI: Making Sense of Raw Evaluation Data

With automation, teams can generate thousands of audio samples and collect as many human evaluations. The real challenge: what to do with all that data?

|2 min read

Ready to unlockthe potential ofyour Voice AI Model?

Improve your model with trust