Gemini 2.5 TTS vs. ElevenLabs: A Side-by-side Performance

Google recently introduced its Gemini 2.5 text-to-speech (TTS) model, drawing attention across the voice AI community. But how does it actually perform when measured against established models like ElevenLabs’ Multilingual V2?

At Podonos, we believe performance claims should be backed by transparent, data-driven analysis. That’s why we conducted a head-to-head evaluation of Gemini 2.5 Flash and ElevenLabs’ latest multilingual model.


Key Findings

1. Overall Performance

Both models scored similarly in user preferences, but ElevenLabs edged ahead slightly in overall quality.

2. Weakness in Address and Number Pronunciation

Both models showed notable difficulty handling addresses and numbers—highlighting a common challenge in TTS robustness.

3. Dialog and Named Entity Handling

Gemini underperformed in dialog-based speech, especially when pronouncing celebrity names and medical terms, suggesting gaps in real-world context handling.

4. Diversity and Inclusion

Gemini showed a notable imbalance in voice quality across genders, performing significantly better on male voices than female voices. This raises concerns around bias and inclusivity in synthesized speech.

You can find more insights in the full reports below.

📝 Naturalness comparison
📝 Preferences


Why This Matters

As voice AI becomes a core interface in digital experiences, accurate and fair performance evaluation is no longer optional. Models must be tested not only for naturalness and clarity, but also for consistency across diverse content and speaker profiles.

At Podonos, our goal is to make this kind of rigorous evaluation accessible to any AI team. Whether you're launching a new model or refining an existing one, Podonos helps you identify blind spots, benchmark against competitors, and make confident improvements.
Other readings

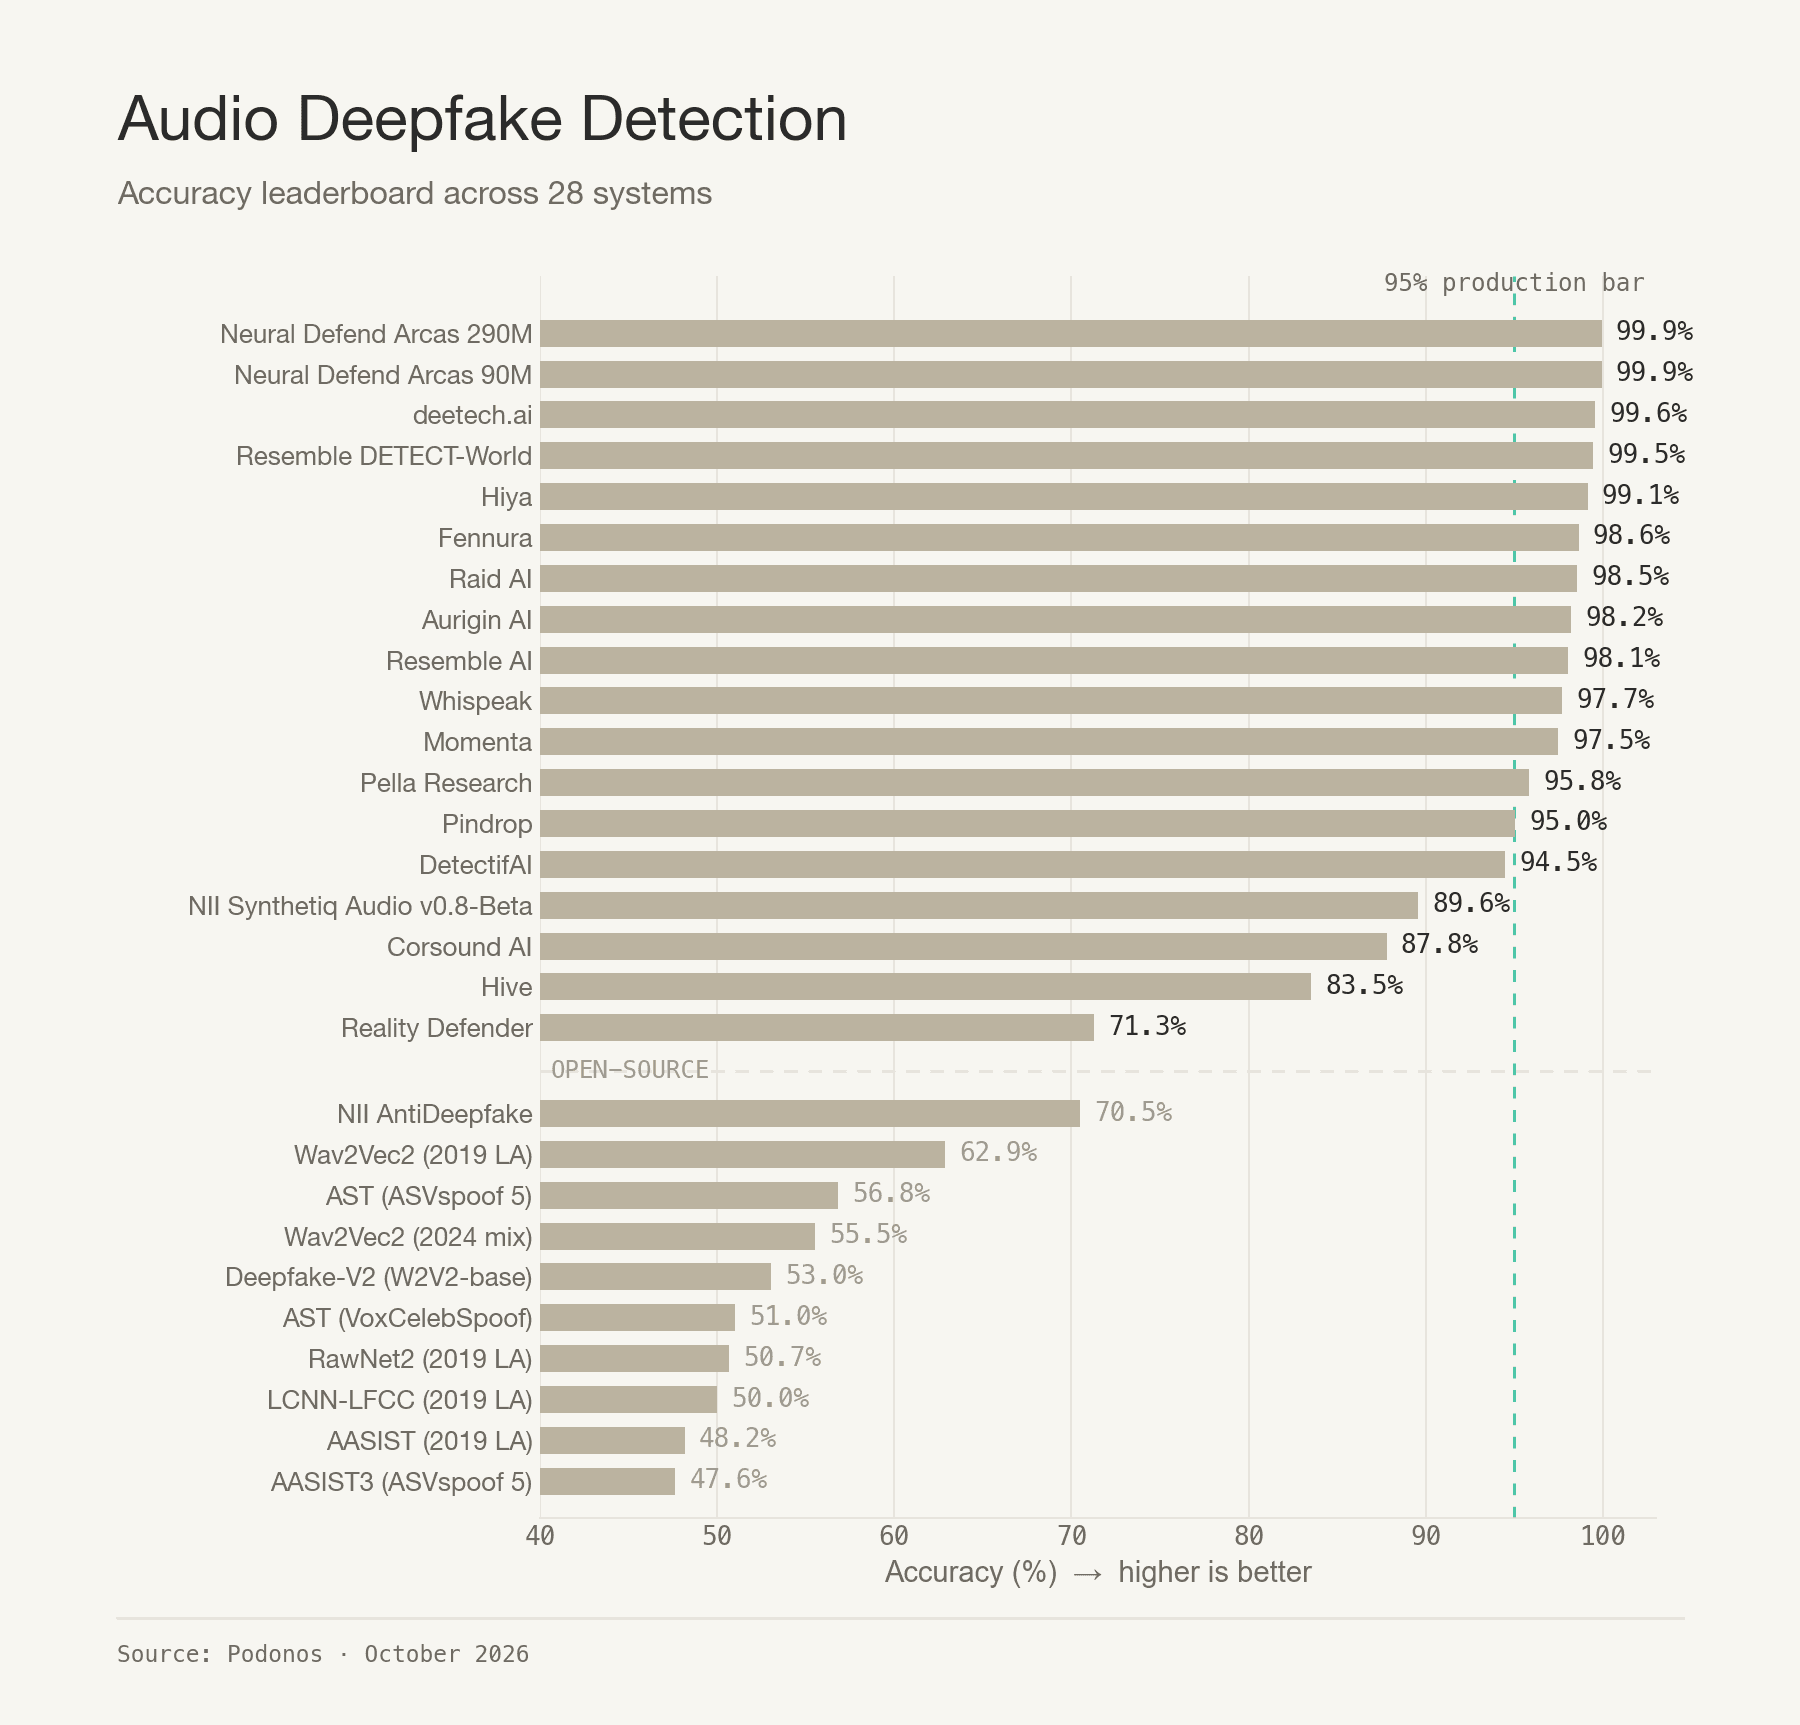
Audio deepfake detection benchmark: Neural Defend leads as 13 systems clear 95%

Five new entries later, our audio deepfake detection benchmark has 28 systems, Neural Defend leads at 99.93%, and 13 systems now clear 95% accuracy.

|7 min read

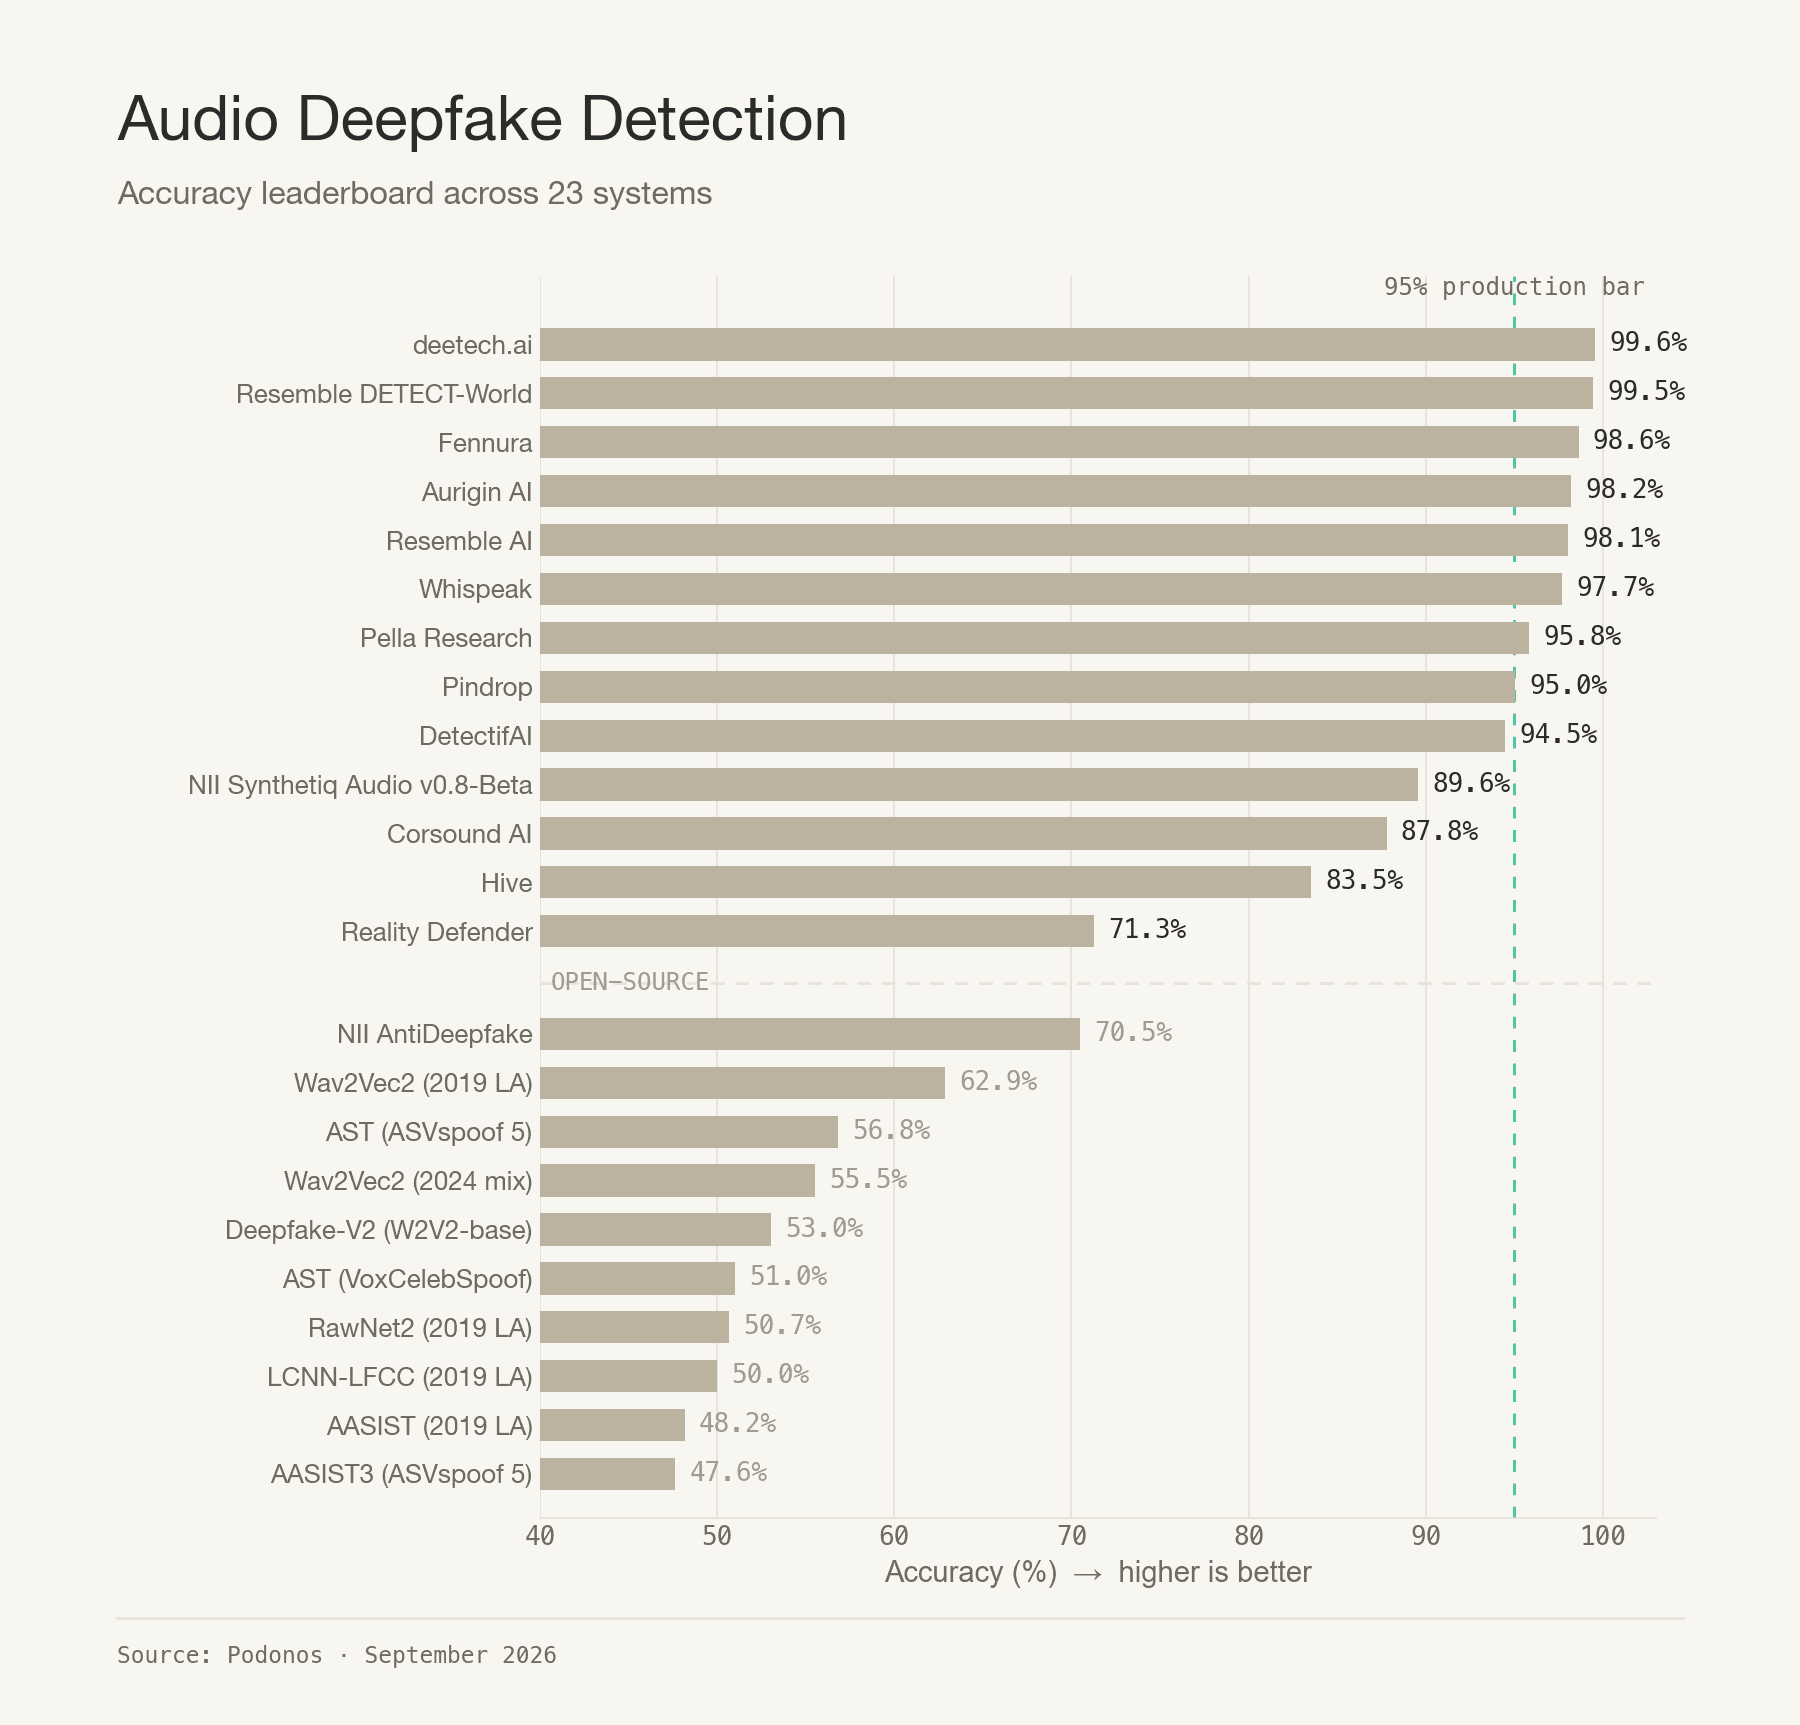
Audio deepfake detection benchmark: deetech.ai takes the top spot

Five new systems later, our audio deepfake detection benchmark has grown to 23 entries, and eight systems now clear 95% accuracy.

|11 min read

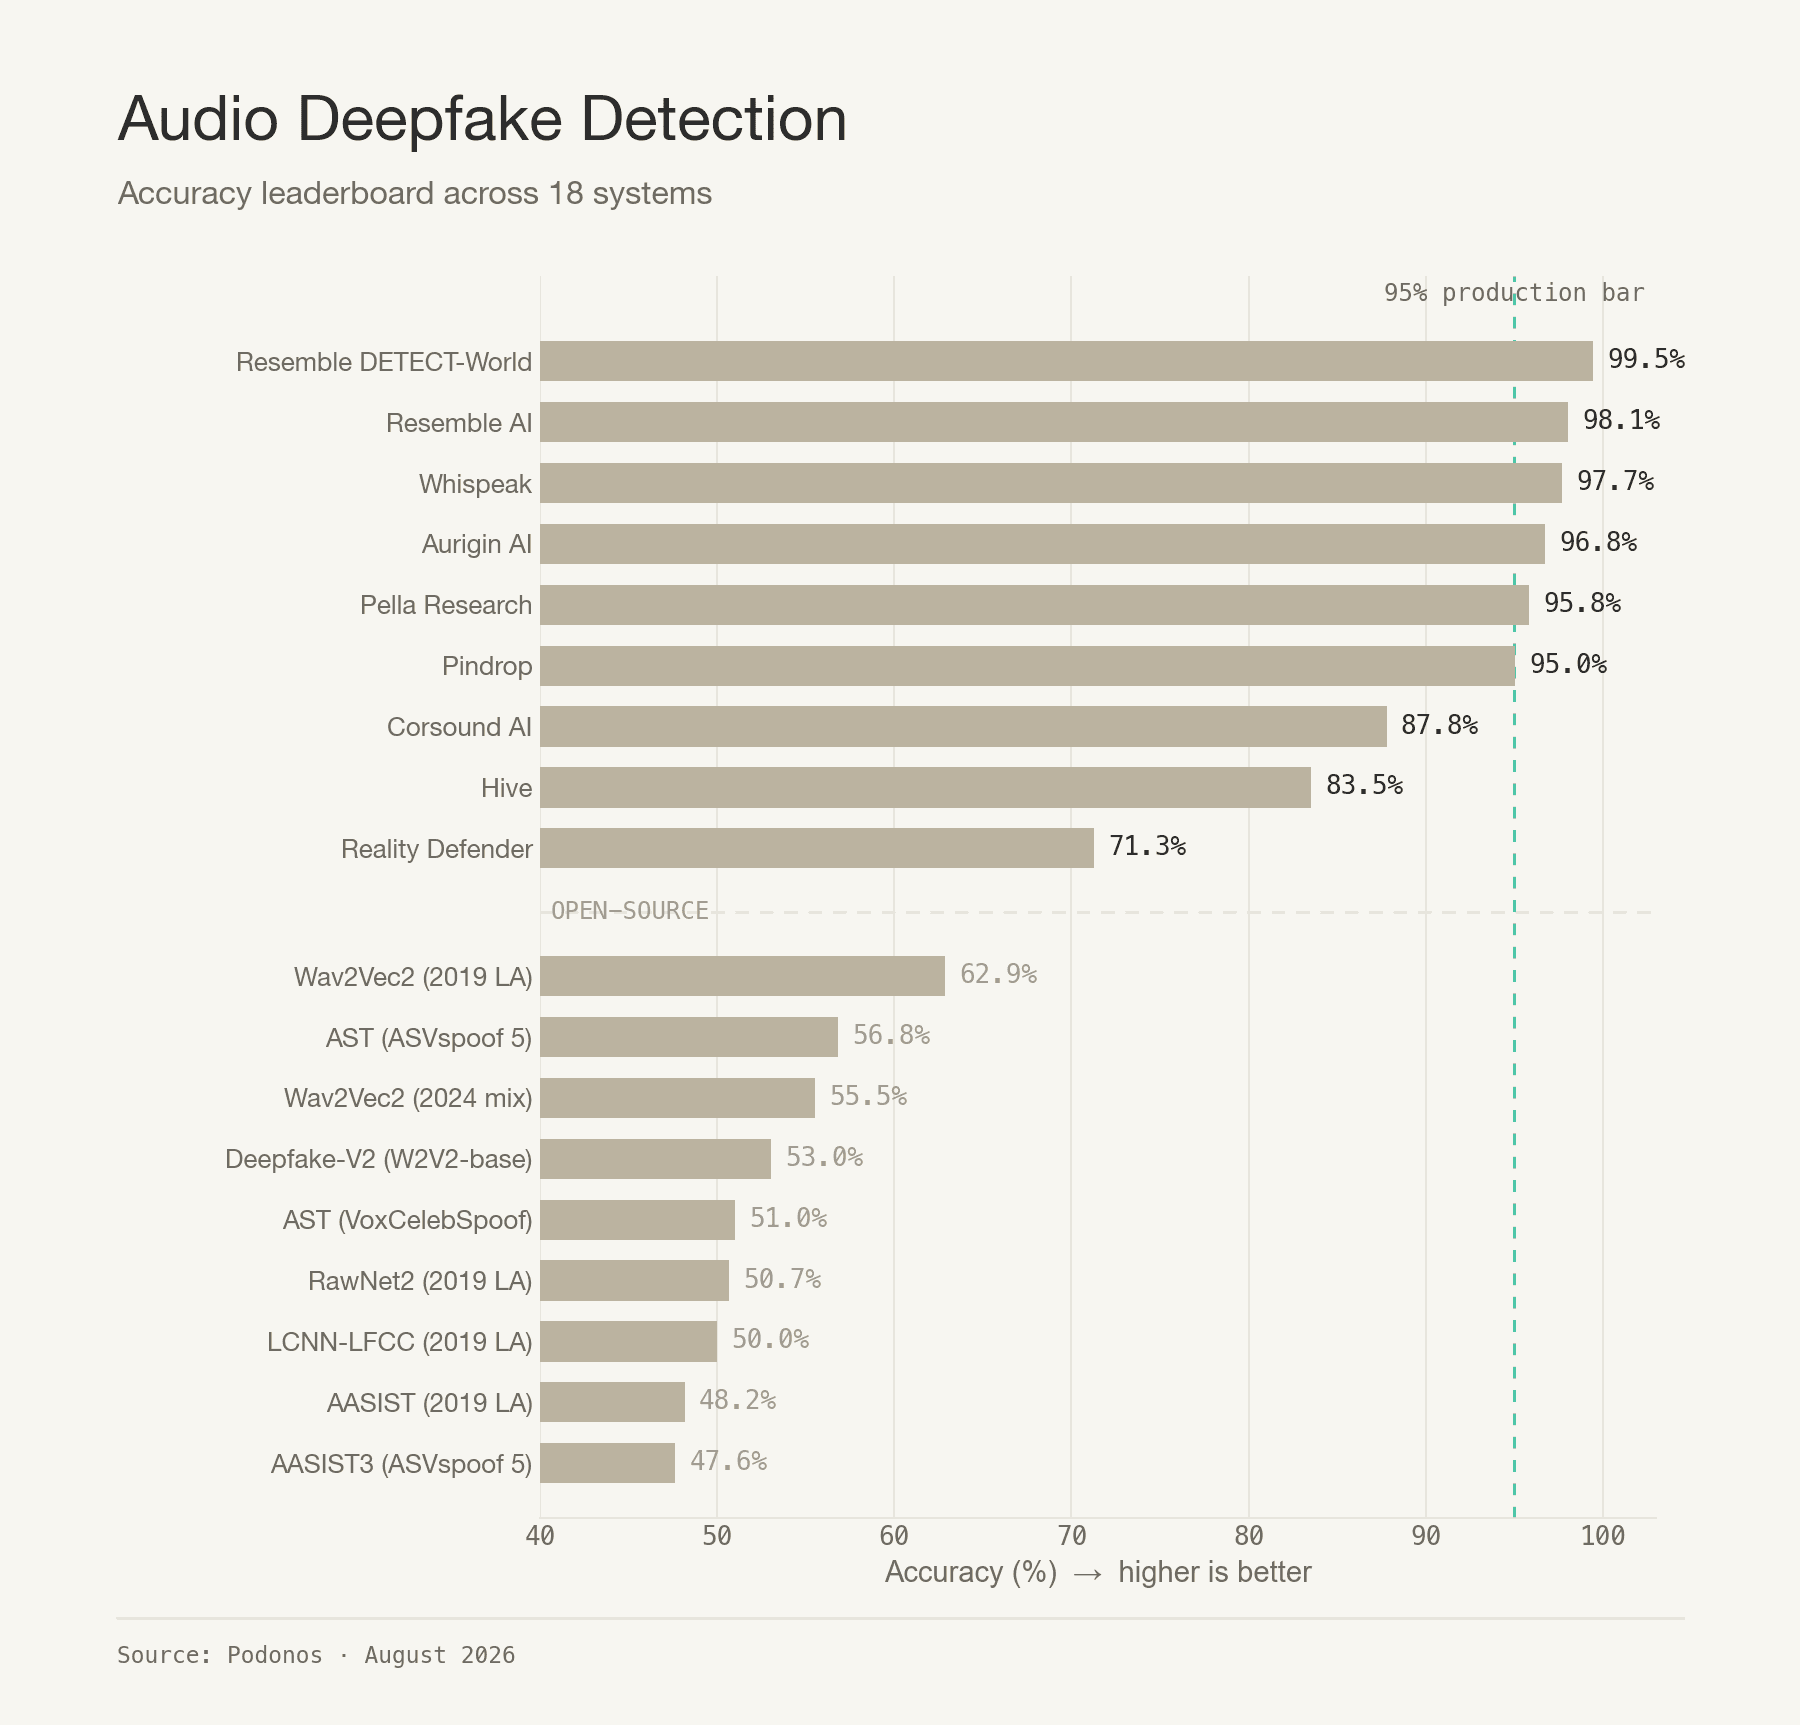
Audio deepfake detection benchmark: an open model finally clears the production bar

When we last published this benchmark, four commercial systems sat above 95% accuracy and none of nine downloadable open-source models scored above 63%.

|10 min read

Audio Deepfake Detection Benchmark: the production bar moves to four

Nine new systems later, the top of our audio deepfake detection benchmark is crowded, the open-source gap is wider than ever, and speed sets systems apart.

|7 min read

Natural ≠ Preferred: What Our TTS Rankings Revealed About How Humans Actually Judge AI Voices

Naturalness and preference diverge: our US English TTS benchmark ranked Deepgram Aura 2 #1 for naturalness and Rime Arcana v3 #1 for preference.

|7 min read

Automatic Deepfake Audio Detection Benchmark

Every audio deepfake vendor reports accuracy around 99%, but none of those numbers are comparable: each comes from a test set the vendor controls.

|7 min read

Announcing the Selected Teams for the Podonos Research Support Program

After meeting speech and audio researchers and reviewing their applications, we announce the teams selected for the Podonos Research Support Program.

|2 min read

Benchmarking Chatterbox Turbo: How Resemble AI Evaluated Open-Source Voice AI with Podonos

Resemble AI's open-source Chatterbox showed open TTS models are viable alternatives to proprietary systems. Chatterbox Turbo takes that a step further.

|5 min read

Introducing Podonos Flash

Human evaluation gives voice AI teams the best insight but takes time, and fast AI evaluators often miss human perception. Podonos Flash changes that.

|4 min read

Podonos just raised $2.4M in pre-seed funding

Podonos has raised $2.4M in pre-seed funding to tackle voice AI evaluation, led by Serac Ventures with participation from Naver D2SF and KAIST Ventures.

|3 min read

Ready to unlockthe potential ofyour Voice AI Model?

Improve your model with trust